AI Document Processing for Businesses: Automate Data Extraction from PDFs, Invoices, and Forms
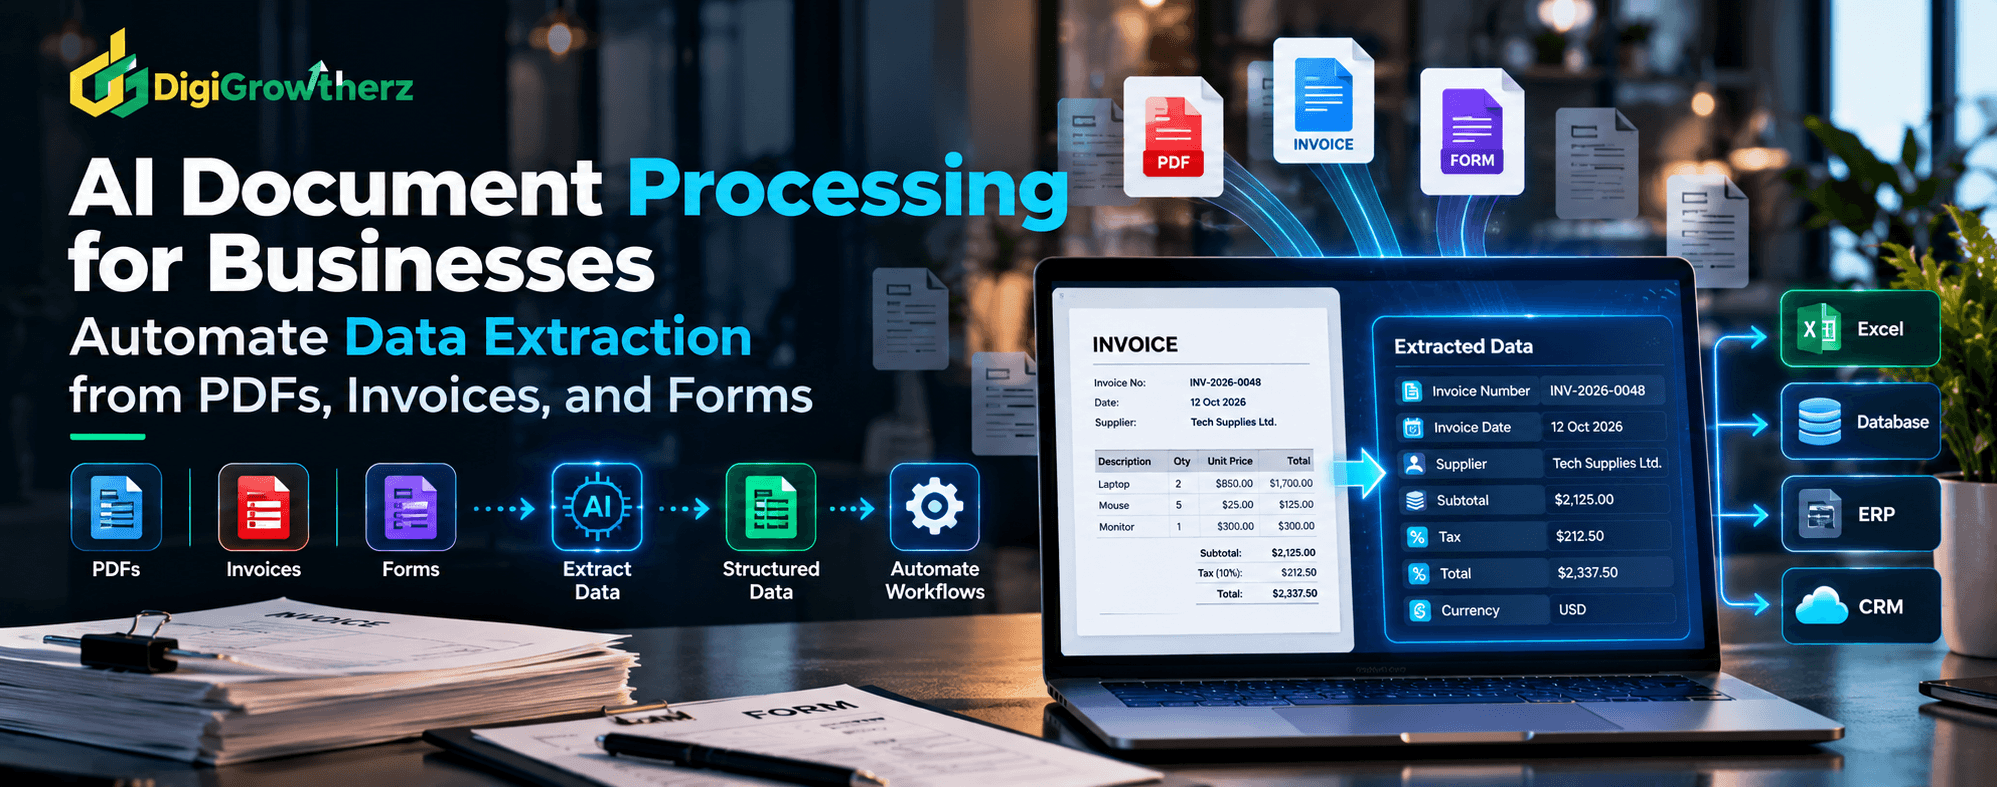
Manually entering information from invoices, PDFs, receipts, and business forms wastes time and creates opportunities for errors. Learn how AI document processing extracts structured data, validates important fields, and connects documents to business workflows while keeping accuracy, security, and human review in focus.
D
DigiGrowtherz
DigiGrowtherz
Invoices arrive as PDFs. Suppliers send quotations in different formats. Customers submit forms, receipts, applications, and scanned documents. Someone then has to open each file, locate the important information, and enter it into a spreadsheet, accounting system, CRM, or another business application.
As document volumes increase, this repetitive work becomes difficult to manage. Manual entry can introduce transcription errors, delay approvals, and consume time that employees could spend on more valuable tasks.
AI document processing offers a way to automate much of this work. Depending on the solution, it can recognise text, identify document types, extract fields such as invoice numbers and totals, and send structured information to other systems.
However, extracting text is not the same as understanding a document, and extracting a value is not the same as verifying that it is correct. A system might recognise an invoice total but still fail to detect a duplicate invoice, an incorrect tax calculation, or a mismatch with a purchase order.
The most effective approach combines document recognition, structured extraction, business-rule validation, and human review where necessary.
This guide explains how AI document processing works, which business tasks benefit most, how to choose an implementation, and how to measure whether automation is worth the investment.
1. What Is AI Document Processing?
AI document processing uses technologies such as optical character recognition (OCR), machine learning, document classification, and information extraction to convert documents into usable data.
Company policies, standard operating procedures (SOPs), manuals, and internal documents are only useful when employees can find the right information quickly. Learn how AI knowledge management helps businesses search internal documents using natural language, retrieve relevant information, generate source-based answers, and improve access to company knowledge while protecting sensitive data.
Instead of treating a file as a page that someone must read manually, the system identifies relevant content and organises it into structured fields.
For example, an invoice might contain:
Supplier name and address.
Invoice number and date.
Purchase order reference.
Currency and payment terms.
Line-item descriptions and quantities.
Subtotal, taxes, and total amount.
Due date and bank details.
A document-processing system can extract these fields and return them as structured data, such as a JSON object or a record that can be passed to an accounting workflow.
The exact fields and reliability depend on the document, the extraction technology, and how the solution is configured.
OCR versus intelligent document processing
OCR identifies text within images or scanned documents. It can also be part of a pipeline that processes documents containing both selectable digital text and scanned pages.
Intelligent document processing goes further by identifying document structure, classifying document types, associating values with their labels, and extracting information into predefined fields.
For example, OCR might recognise the text “Total: 1,250.00”. A document-processing model must also identify that 1,250.00 is the total amount, distinguish it from a subtotal, determine the currency where possible, and return the value in the expected format.
For documents with varied layouts, this additional understanding is particularly useful.
Official services illustrate these capabilities. Google Cloud Document AI documents OCR, form parsing, and custom extraction options, while Amazon Textract supports text, key-value pairs, tables, and other document structures. Microsoft's Document Intelligence documentation describes similar extraction capabilities.
These are examples of available approaches, not guarantees that any single service will handle every document accurately.
2. How AI Document Processing Works
A reliable system does more than send a PDF to an AI model. It follows a defined pipeline that controls how files enter the system, how information is extracted, and what happens before the results are used.
Step 1: Receive the document
Documents may arrive through an email inbox, website upload, shared folder, cloud storage, supplier portal, or an existing business application.
The system records the file's source, identifier, arrival time, and other necessary metadata. It should also check that the file type is permitted and that the document can be processed safely.
For example, a finance workflow might monitor a designated invoice inbox and create a processing task whenever a new attachment arrives.
Step 2: Classify the document
Before extracting fields, the system may need to identify whether a file is an invoice, receipt, purchase order, application form, or another document type.
Classification helps select the appropriate extraction model or rules. A customer application and a supplier invoice have different fields, so applying the wrong extraction process can produce incomplete or misleading results.
If the file contains multiple document types, a suitable system may also need to split it into individual documents.
Step 3: Read the content
OCR or document parsing extracts text and, where supported, information about layout, tables, checkboxes, and the position of each item on the page.
For a digitally generated PDF, text may already be available. A scanned paper document, by contrast, may require OCR.
Image quality matters. Low-resolution scans, skewed pages, handwriting, unusual layouts, stamps, and overlapping text can affect extraction quality.
Step 4: Extract structured fields
The system identifies the information the business needs and maps it to a defined schema.
An invoice-processing workflow might convert a document into a record such as:
Field
Extracted value
Supplier
Example Supplies Ltd.
Invoice number
INV-2048
Invoice date
12 October 2026
Currency
USD
Subtotal
1,000.00
Tax
100.00
Total
1,100.00
This is an illustrative example, not the output of a real invoice. In a production workflow, each value must be linked to the relevant source document and validated before it is used.
Step 5: Validate the extracted data
The system checks whether required fields are present, values use the expected formats, totals reconcile, and records match relevant business rules.
For instance, an invoice total may need to equal the subtotal plus tax, subject to any discounts, fees, rounding rules, or other adjustments.
The workflow can also check whether an invoice number already exists or whether a supplier is an approved vendor.
These checks are essential because a system can extract a value correctly from a document that is itself incorrect.
Step 6: Send the data to the destination system
After validation, the system can pass the structured record to an accounting application, ERP, CRM, spreadsheet, database, or approval workflow.
If the result is incomplete or uncertain, the document should be routed for review rather than silently pushed into the next system.
This combination of extraction, validation, and controlled integration turns document processing into an operational business workflow.
3. Common Business Use Cases
The most suitable tasks usually involve recurring documents with information that employees repeatedly read, copy, compare, or enter into software.
Automated invoice processing
Accounts teams can use document processing to extract supplier details, invoice references, line items, dates, tax amounts, and payment totals.
The extracted information can then be checked against supplier records and purchase orders before entering the accounts-payable workflow.
Automation can reduce manual data entry, but approval and payment controls should remain separate. Extracting an invoice successfully does not establish that the invoice is legitimate, that the goods were received, or that the payment is authorised.
Purchase order and quotation processing
Businesses often receive purchase orders and quotations in different formats. AI can extract product descriptions, quantities, unit prices, delivery terms, and reference numbers.
A workflow can compare these fields with internal records and highlight discrepancies for procurement staff.
Where products use inconsistent naming or units, additional matching logic may be required. Similar-looking descriptions should not be treated as identical products without appropriate checks.
Receipt and expense processing
A business can extract dates, merchant names, currencies, totals, and expense categories from receipts.
The system may then create a draft expense record for the employee or finance team to review.
Receipts can be particularly challenging because they may be photographed at an angle, poorly lit, faded, or printed on narrow paper. A review path is important when the amount or supporting details cannot be reliably established.
Customer and supplier forms
Registration forms, onboarding forms, applications, and supplier questionnaires may contain names, contact information, addresses, dates, selections, and declarations.
AI processing can transfer these details into the appropriate system and flag missing or inconsistent fields.
Businesses should avoid treating extraction as identity verification or approval. Those are separate checks with their own requirements.
Contracts and business documents
For contracts and agreements, a system may identify document types, extract selected clauses, locate dates, and highlight fields such as renewal periods or termination notices.
Because legal meaning depends on context, exceptions, and exact wording, extracted contract information should not replace professional review where legal or commercial consequences are significant.
4. AI Document Processing vs Manual Entry and Traditional Automation
Not every business needs an AI document-processing platform. The right approach depends on document volume, format consistency, the importance of accuracy, and the available software.
Approach
Best suited for
Main limitation
Manual entry
Low volumes or documents requiring individual judgement
Time-consuming and susceptible to transcription mistakes
Templates and rules
Stable documents with predictable layouts
Layout changes can break extraction rules
OCR with rules
Documents where text recognition and predefined patterns are sufficient
Recognising text does not always identify the meaning of each field
AI-powered document processing
Varied layouts, forms, tables, and less-structured documents
Requires testing, validation, and exception handling
Hybrid processing
Repetitive extraction combined with business rules and human review
Needs clear workflow design and monitoring
Template-based extraction can be effective when a company receives the same form every time. For example, a fixed internal form may need little more than OCR and field-position rules.
AI-based extraction becomes more attractive when documents vary in layout or when the same information appears in different places across files.
A hybrid system is often the most practical choice. AI extracts the information, conventional code checks the business rules, and employees review cases that do not meet the required criteria.
5. How to Choose the Right Document Processing Solution
Before choosing a vendor or building a custom solution, evaluate the documents and outcomes involved.
Start with the documents you actually receive
Collect representative samples from the real workflow, including different suppliers, layouts, page counts, scan qualities, and edge cases.
A solution that works on clean sample PDFs may perform differently on photographs, multi-page forms, handwritten notes, or tables with merged cells.
The initial evaluation should reflect the actual documents the business expects to process.
Check field-level extraction requirements
Make a list of every field the system needs to extract and identify which fields are most important.
For example, an invoice reference may be needed to link a payment to a record, while the total amount affects financial processing. Errors in these fields can have different consequences and may require different review thresholds.
Check whether the solution supports the required currencies, languages, tables, checkboxes, document formats, and custom fields.
Compare prebuilt and custom models
Prebuilt models can be convenient for common document types such as invoices or receipts. They may reduce initial setup when their available fields and supported document types match the business requirements.
Custom models may be more suitable when the business uses specialised forms, industry-specific fields, or unusual layouts.
Customisation can require labelled examples, evaluation, and ongoing maintenance as documents change. It should not be assumed to guarantee higher accuracy in every case.
Evaluate the complete integration
A tool that extracts fields well may still be unsuitable if it cannot integrate reliably with the accounting system, database, or workflow platform the business uses.
Check how the service returns results, handles failed requests, supports authentication, processes multi-page documents, and communicates extraction errors.
Also check current usage limits, available regions, supported formats, and pricing directly with each provider. These details vary across services and can change over time.
6. Accuracy, Confidence Scores, and Human Review
One of the most important design decisions is determining when an extracted result can be accepted automatically and when it needs human review.
Document-processing systems can return confidence scores for some extracted fields. These scores estimate how strongly the model supports a prediction; they are not a guarantee that the value is correct.
A missing category in a low-risk internal document might be acceptable for automated processing. An uncertain invoice total or bank account number should receive more scrutiny.
Use a review policy that considers both the extraction confidence and the consequence of an error.
Do not apply one arbitrary threshold to every field. Establish thresholds through testing on representative documents and measure how often accepted fields are correct.
Validate using business rules
Confidence scores alone are not enough. Use deterministic checks wherever possible.
For example:
Verify required fields are present.
Check that dates and currency values use accepted formats.
Recalculate totals using the document's stated rules.
Compare supplier names and references with approved records.
Detect duplicate invoice identifiers.
Match invoices against purchase orders or receipt records where available.
Flag impossible, inconsistent, or suspicious values.
A value may be extracted with high confidence but still be wrong because the source document contains an error or because a similar field was confused with the intended one.
Keep a human review path
When critical values are missing, inconsistent, or uncertain, direct the record to a reviewer.
A useful review screen shows the extracted value alongside the relevant portion of the original document. This lets the employee confirm or correct the field without searching through the entire file.
Corrections can also reveal repeated weaknesses in a document template or extraction configuration, allowing the workflow to improve over time.
7. Integrating Document Processing Into Business Workflows
Data extraction becomes more valuable when it connects to the system where the information needs to be used.
For example, an invoice workflow can follow this sequence:
Receive an invoice attachment.
Check the file and classify the document.
Extract supplier details, line items, dates, and amounts.
Validate required fields and calculations.
Check for duplicates and match available purchase-order records.
Route exceptions for human review.
Create a draft accounts-payable record.
Send the record through the existing approval process.
Log the result and retain the required supporting documentation.
The same general architecture can be applied to receipts, customer applications, purchase orders, and supplier forms.
Use APIs and workflow automation
Many document-processing services expose APIs or SDKs that let applications submit files and receive structured results. A workflow engine can coordinate the steps around that service.
Depending on the business's needs, the system may use webhooks, scheduled jobs, queues, database records, or direct API calls.
For larger document batches or long-running processing jobs, asynchronous processing may be more appropriate than waiting for every file to finish during a user request. The exact architecture depends on document size, service limits, throughput, and how quickly the results are needed.
Build for failure and recovery
Documents may be unreadable, incomplete, duplicated, or incompatible with the chosen processor. Integrations can also fail temporarily.
A reliable workflow should record the processing status, preserve the original document, provide a way to retry safely, and prevent duplicate records when a job is submitted more than once.
Without this protection, a failed response or repeated event could create duplicate invoices or inconsistent business records.
8. Security and Privacy Considerations
PDFs and forms can contain personal details, bank information, contracts, customer records, and other confidential data. The workflow must protect that information from collection through processing, storage, review, and deletion.
Restrict access and permissions
Use role-based access controls so employees and services can access only the documents and fields needed for their work.
Protect API credentials, use secure connections, and keep records of important processing actions. Do not expose uploaded documents or extracted data through public URLs or unrestricted storage locations.
Review provider data handling
Before sending documents to a third-party service, review its terms and documentation for data retention, processing locations, encryption, access controls, logging, and any permitted use of submitted information.
Cloud providers differ in their configurations and service terms. Do not assume that every plan or setup provides the same protection by default.
For example, Google Cloud's Document AI security documentation describes its service-specific handling and controls, while Amazon Textract's data protection guidance discusses access management, encryption, and other security considerations. These are useful starting points for evaluating each provider, not a substitute for reviewing your own configuration and contractual requirements.
Minimise sensitive data
Process only the information required for the business purpose. Avoid copying unnecessary personal or financial data into logs, notifications, or debugging records.
Set retention rules for original files, extracted records, and temporary processing data. Where relevant, review obligations under applicable privacy and data-protection laws.
Treat uploaded documents as untrusted input
If extracted text is later sent to a generative AI model, a document could contain misleading or malicious instructions. An AI model must not be allowed to treat arbitrary document content as an instruction to change permissions, reveal unrelated data, or initiate unauthorised actions.
Use restricted permissions, validate outputs, isolate processing steps where appropriate, and require approval for sensitive actions. Extraction should not automatically authorise a payment, change a supplier's bank details, or approve a contract.
9. Measuring ROI From AI Document Processing
A document-processing project should be evaluated using observed results rather than assumptions about how much time AI will save.
Track the existing process before implementation and compare it with a pilot using representative documents.
Useful measures include:
Average staff time spent processing each document.
Extraction accuracy for critical fields.
Percentage of documents requiring manual review.
Rework caused by missing or incorrect data.
Time from document receipt to completion.
Duplicate or failed records.
Cost per successfully processed document.
Total cost of software, integrations, maintenance, and review.
Calculate the potential time savings
Suppose a business processes 300 documents per month, and each takes an average of four minutes to enter manually. That represents 1,200 minutes, or 20 hours, of manual entry per month.
If a tested workflow reduces the average manual effort to one minute per document, the remaining entry work would be five hours. The potential reduction is 15 hours per month before accounting for review, exceptions, maintenance, or other operating costs.
This is an illustrative calculation, not an industry benchmark or a prediction of performance. The actual benefit depends on document quality, processing accuracy, the number of exceptions, and the time needed to validate results.
The financial case is strongest when a business measures the time actually recovered, the cost of correcting errors, and the full operating cost of the new workflow.
10. Common Mistakes to Avoid
Automating before standardising the process. If employees use inconsistent approval rules or data formats, automation can reproduce the same inconsistency at scale. Document the process first.
Assuming OCR guarantees accurate extraction. Reading text and identifying the correct business field are different tasks. Test extraction on real documents and validate critical values.
Ignoring unusual documents. Different suppliers, layouts, languages, and scan qualities may produce different results. Include difficult examples in your evaluation.
Automatically approving financial actions. Extracted data should not replace approval controls, duplicate checks, purchase-order matching, or payment verification.
Choosing a tool only by its model claims. Evaluate extraction accuracy, supported formats, integration capabilities, limits, operating costs, and security requirements in the context of your use case.
Ignoring ongoing maintenance. Document templates change, integrations fail, and business rules evolve. Assign responsibility for monitoring and updating the system.
Failing to plan for exceptions. A solution that works only when every document is perfect is unlikely to be dependable in everyday operations. Provide clear review and recovery paths.
11. A Practical Implementation Roadmap
Businesses can reduce risk by introducing AI document processing in stages.
Phase 1 — Choose a specific document type. Start with a recurring task, such as extracting invoice data or processing customer forms.
Phase 2 — Collect representative samples. Include normal, unusual, and poor-quality documents. Define the fields that must be extracted and what counts as an acceptable result.
Phase 3 — Select the extraction approach. Evaluate OCR, prebuilt document models, custom extraction, and conventional rules against your actual documents. Choose the simplest approach that meets the requirements.
Phase 4 — Build validation and review. Add checks for required fields, calculations, duplicates, and business rules. Establish human-review thresholds based on risk and observed results.
Phase 5 — Connect the destination system. Transfer validated records through supported integrations, while preserving the source documents and processing history.
Phase 6 — Pilot and measure. Compare accuracy, processing time, exception rate, and total costs against the existing process. Correct weaknesses before expanding.
Phase 7 — Scale responsibly. Add other document types only after the first workflow demonstrates dependable results. Review access controls, retention, monitoring, and recovery procedures as the system grows.
The schedule and effort will depend on the documents, integrations, compliance obligations, and quality requirements involved. A straightforward workflow may need less work than one involving multiple enterprise systems and sensitive financial records.
Conclusion
AI document processing can help businesses turn information locked inside PDFs, invoices, receipts, and forms into structured data that other systems can use.
The strongest solutions combine OCR and intelligent extraction with validation, workflow automation, human review, and appropriate security controls. They are designed for the actual documents a business receives, rather than relying on ideal sample files or broad claims about accuracy.
Start with a specific, repetitive process. Define the fields that matter, test real documents, validate important values, and measure the time and cost saved. Keep human approval for financial, legal, or otherwise consequential decisions.
The goal is not simply to extract more data automatically. It is to make document-heavy processes more efficient while keeping the results accurate, auditable, and dependable.
Explore AI Automation With DigiGrowtherz
Every business has different documents, software systems, and approval requirements. DigiGrowtherz helps businesses explore practical automation opportunities that fit their workflows and operational needs.
Learn how to automate customer support across email, website chat, WhatsApp, and other messaging channels. This guide explains how to centralise conversations, use AI to answer routine questions, route enquiries, protect customer data, and transfer complex cases to human support teams while keeping service quality and customer trust at the centre.
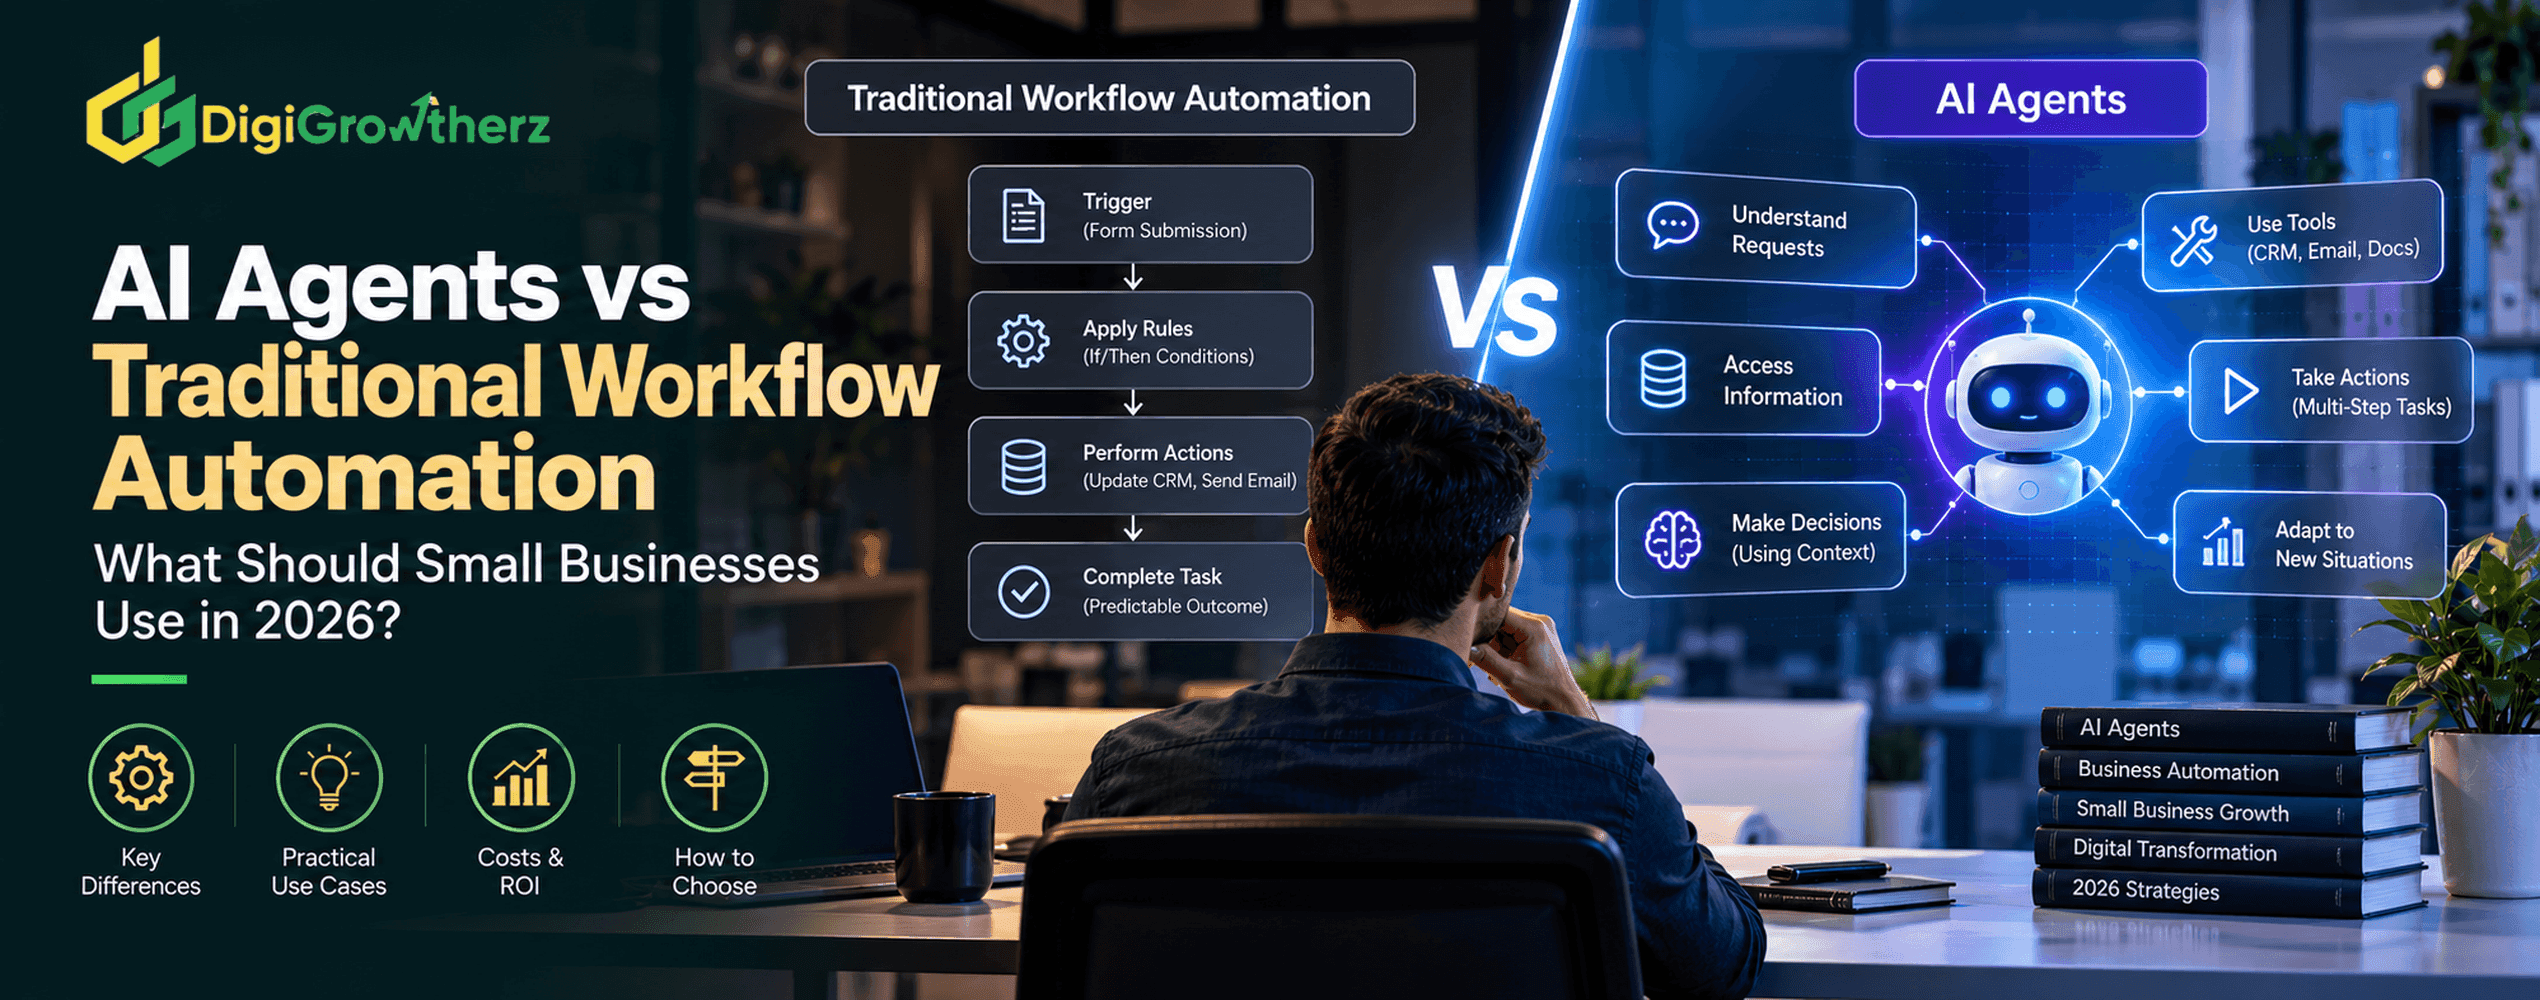
AI agents can handle flexible, multi-step tasks, while traditional workflow automation excels at predictable, rule-based processes. Learn how they differ, when each approach makes sense, what they cost to operate, and how small businesses can combine them to improve efficiency without adding unnecessary complexity.